
AIMET is a software toolkit for quantizing trained ML models.
AIMET improves the runtime performance of deep learning models by reducing compute load and memory footprint. Models quantized with AIMET facilitate its deployment on edge devices like mobile phones or laptops by reducing memory footprint.
AIMET employs post-training and fine-tuning techniques to minimize accuracy loss during quantization and compression. AIMET supports models from the ONNX and PyTorch frameworks.

AIMET is designed to work with PyTorch and ONNX models.
You can find models quantized with AIMET on Qualcomm AI Hub Models - a collection of optimized and quantized models.

- Advanced quantization techniques: Inference using integer runtimes is significantly faster than using floating-point runtimes. For example, models run 5x-15x faster on the Qualcomm Hexagon DSP than on the Qualcomm Kyro CPU. In addition, 8-bit precision models have a 4x smaller footprint than 32-bit precision models. However, maintaining model accuracy when quantizing ML models is often challenging. AIMET solves this using novel techniques like Data-Free Quantization that provide state-of-the-art INT8 results on several popular models.
- Supports advanced model compression techniques that enable models to run faster at inference-time and require less memory
- AIMET is designed to automate optimization of neural networks avoiding time-consuming and tedious manual tweaking. AIMET also provides user-friendly APIs that allow users to make calls directly from their PyTorch pipelines.
Please visit the AIMET on Github Pages for more details.
aimet-onnx and aimet-torch is available on PyPI.
Check our Quick Start to get started with latest AIMET package.
To build the latest AIMET code from the source, see Build, install and run AIMET from source in Docker environment
Check out guide to get started on PTQ technique.
Following table summarizes basic technique such as Calibration to advanced techniques such as SeqMSE and Adaptive Rounding(AdaRound) that you can use with AIMET.
| Technique | ONNX | PyTorch | What does it do? |
|---|---|---|---|
| Calibration | ✅ | ✅ | Computes Quantization parameters |
| AdaRound | ✅ | ✅ | Rounds quantized weights |
| SeqMSE | ✅ | ✅ | Optimizes encodings for each layer |
| BatchNorm Folding | ✅ | ✅ | Folds batchnorm to bridge the gap between simulation and on-target |
| Cross Layer Equalization | ✅ | ✅ | Rescales the weight to reduce range imbalance |
| BatchNorm re-estimation | ✅ | ✅ | Re-estimates batchnorm statistics |
| AdaScale | ✅ | ✅ | Learns per-weight scales via blockwise optimization to minimize quantization error |
| OmniQuant | ❌ | ✅ | Optimizes quantized weights |
| SpinQuant | ✅ | ✅ | Reduces activation outliers via Hadamard rotations |
AIMET supports Quantization Aware Training(QAT) via aimet-torch.
If you want to use both QAT and some of the advanced PTQ techniques from AIMET, we recommend the following workflow:
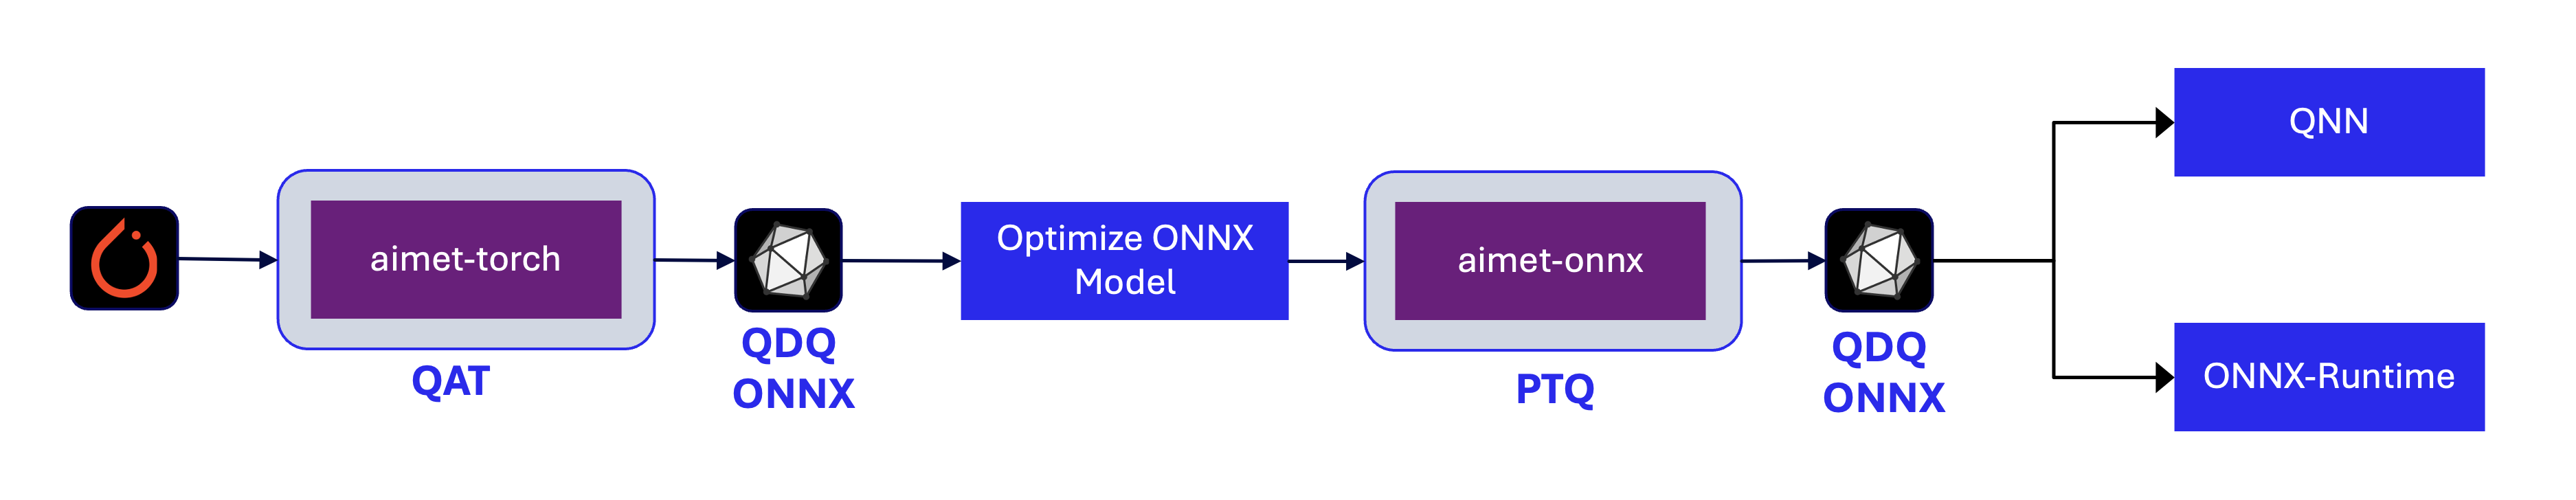
Check detailed QAT guide here
- Spatial SVD: Tensor decomposition technique to split a large layer into two smaller ones
- Channel Pruning: Removes redundant input channels from a layer and reconstructs layer weights
- Per-layer compression-ratio selection: Automatically selects how much to compress each layer in the model
- Weight ranges: Inspect visually if a model is a candidate for applying the Cross Layer Equalization technique. And the effect after applying the technique
- Per-layer compression sensitivity: Visually get feedback about the sensitivity of any given layer in the model to compression
AIMET can quantize an existing 32-bit floating-point model to an 8-bit fixed-point model without sacrificing much accuracy and without model fine-tuning.
The DFQ method applied to several popular networks, such as MobileNet-v2 and ResNet-50, result in less than 0.9% loss in accuracy all the way down to 8-bit quantization, in an automated way without any training data.
| Models | FP32 | INT8 Simulation |
|---|---|---|
| MobileNet v2 (top1) | 71.72% | 71.08% |
| ResNet 50 (top1) | 76.05% | 75.45% |
| DeepLab v3 (mIOU) | 72.65% | 71.91% |
For this example ADAS object detection model, which was challenging to quantize to 8-bit precision, AdaRound can recover the accuracy to within 1% of the FP32 accuracy.
| Configuration | mAP - Mean Average Precision | ||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FP32 | 82.20% | ||||||||||||||
| Nearest Rounding (INT8 weights, INT8 acts) | 49.85% | ||||||||||||||
| AdaRound (INT8 weights, INT8 acts) | 81.21% | ||||||||||||||
For some models like the DeepLabv3 semantic segmentation model, AdaRound can even quantize the model weights to 4-bit precision without a significant drop in accuracy.
| Configuration | mIOU - Mean intersection over union | ||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| FP32 | 72.94% | ||||||||||||||
| Nearest Rounding (INT4 weights, INT8 acts) | 6.09% | ||||||||||||||
| AdaRound (INT4 weights, INT8 acts) | 70.86% | ||||||||||||||
AIMET supports quantization simulation and quantization-aware training (QAT) for recurrent models (RNN, LSTM, GRU). Using QAT feature in AIMET, a DeepSpeech2 model with bi-directional LSTMs can be quantized to 8-bit precision with minimal drop in accuracy.
| DeepSpeech2 (using bi-directional LSTMs) |
Word Error Rate |
|---|---|
| FP32 | 9.92% |
| INT8 | 10.22% |
AIMET can also significantly compress models. For popular models, such as Resnet-50 and Resnet-18, compression with spatial SVD plus channel pruning achieves 50% MAC (multiply-accumulate) reduction while retaining accuracy within approx. 1% of the original uncompressed model.
| Models | Uncompressed model | 50% Compressed model |
|---|---|---|
| ResNet18 (top1) | 69.76% | 68.56% |
| ResNet 50 (top1) | 76.05% | 75.75% |
Thanks for your interest in contributing to AIMET! Please read our Contributions Page for more information on contributing features or bug fixes. We look forward to your participation!
AIMET aims to be a community-driven project maintained by Qualcomm Innovation Center, Inc.
AIMET is licensed under the BSD 3-clause "New" or "Revised" License. Check out the LICENSE for more details.